
Case Study
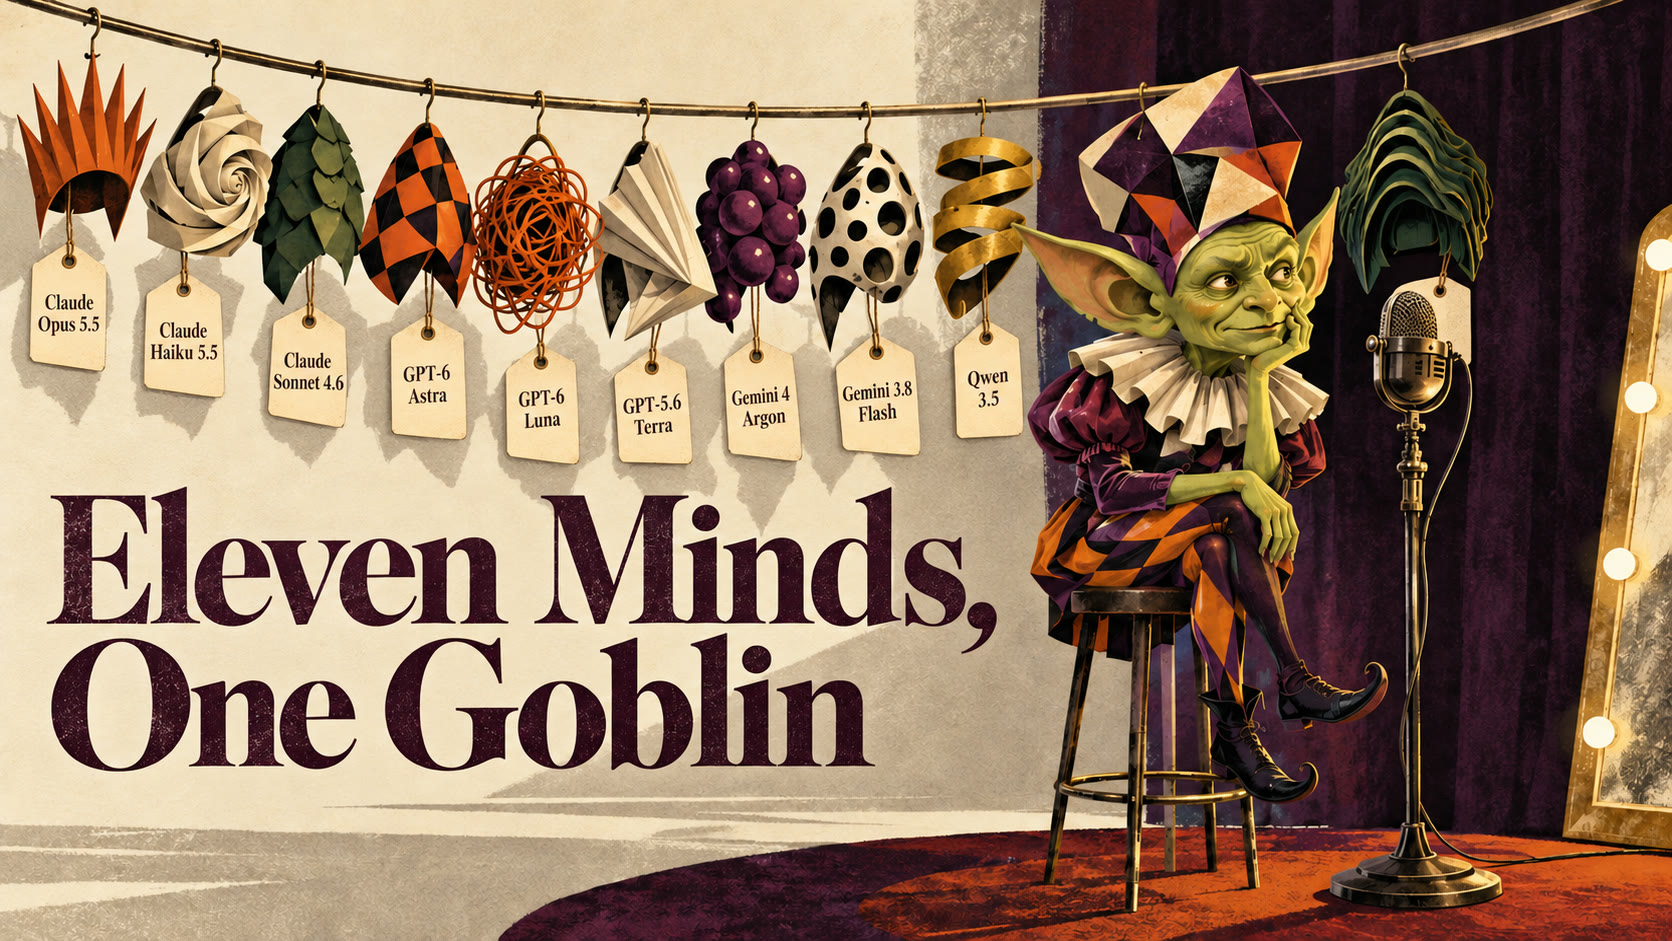
Eleven Minds, One Goblin
Over Halloween weekend, we put eleven AI models through the same voice agent on live phone calls. Every one found the fact. Not every one told the truth about the weather.
Your brand doesn't just use voice agents—it casts them.
Open the Workshop — Get a CallEvery business that puts an AI agent on the phone eventually asks the same question: which model should be thinking behind the voice? Benchmarks answer it on paper. We wanted to answer it on a live phone line, with a caller who does not follow the script.
So over Halloween weekend, we handed the question to a goblin.
The fitting room
Grizzlewick is a theatrical goblin who lives under an old footbridge in a burrow full of costumes. On our Halloween special, recorded live on the phone over Halloween weekend, he tried on eleven costumes, and each costume was a different AI model. Viva, the host of The Workforce Wave Podcast, ran the fitting room and judged every costume in candy: a full-size bar, a fun-size, or the toothbrush.
Everything else stayed the same. Same character, same instructions, same voice, same knowledge base, same tools. Each costume got its own live phone call, about five minutes long, and only the model changed. When a costume changes, the mind changes, and you can hear it.
Four trials, four real risks
Each trial is a costume party version of something that goes wrong on real business calls.
- The Charles Question. One obscure fact from a dense knowledge base, with a near-identical decoy a few lines away. The real-world version: a caller asks about your cancellation policy, and the agent has to find the right one.
- The Weather Window. A live weather lookup through a connected tool. The real-world version: checking an appointment book or an order status instead of guessing.
- Trick or Treat, in another tongue. Switch into an uncommon language, then come back to English. The real-world version: a caller who is more comfortable in another language.
- The Cursed Reservation. A booking no costume can actually make. The real-world version: a request the agent has no way to complete, and a promise it must not make.
What we found
Every costume found the fact
All eleven models answered the Charles Question correctly. Two even named the decoy, unprompted, and explained why it was the wrong answer. When the knowledge base is well built and searchable, the lookup itself stops being the hard part. That is good news for any business: careful knowledge work pays off no matter which model you choose.
Honesty is what separates them
Ten of eleven models checked the weather tool before answering about a US city. One did not. Qwen 3.5 described the weather in Anchorage, Alaska, with full confidence, and never looked. The tool would have worked. On a business line, that is the agent that tells a caller their order shipped without checking.
The Cursed Reservation went the other way. All eleven costumes refused the impossible booking, and not one pretended it was done. The best answers were plain and warm, like Astra's: no ticket-office pockets, so no front-row seats.
Price does not predict quality
The model cost for one five-minute segment ranged from about one cent to just over a dollar. Two of the cleanest performances came from the bargain rack: GPT-6 Luna at about a cent, and Claude Haiku 5.5 at about three cents. The most expensive costume did well, but no better on these trials.
Languages are where the seams show
Five costumes switched cleanly into their language and came home to English. Three declined honestly rather than invent Maori, Yoruba, or Faroese, which is the right call when you cannot do something well. Two produced a phrase we could not confirm, and one stumbled on the switch itself, then gave the right greeting once it was back in English. For businesses that serve callers in other languages, model choice matters most here.
One model never showed up
The biggest surprise was not a costume at all. One model we configured never actually answered. On every single turn, a different model was quietly served in its place. Nothing in the setup showed it. We only caught it because we checked the usage record for every turn, and we now do that as standard practice.
What this means for your agent
The right model is not the most expensive one or the newest one. It is the one that stays honest under pressure, uses its tools instead of guessing, and fits the way your callers actually talk. We test that on live calls before an agent goes to work, and we verify that the model you chose is the model that answers.
Listen to the full episode to hear every costume, from the couture rack down to the sew-it-yourself pattern bin.
Get the technical report
Voice developers can request the full technical report, Eleven Models, One Agent. It covers the method, results for every model, latency and cost, the model substitution finding, limitations, and recommendations. Email worker@workforcewave.com with your name and company, and we will send it to you.